My name is Christopher Bojarski. I'm a web developer, programmer and blogger. Fan of all things technology related. Avid reader and traveler. Married and living in Philadelphia. Connect with me at cbojar.net.
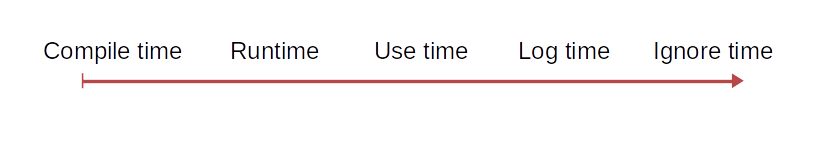
As software developers, we see errors every day. They manifest as exceptions or segfaults or error codes, telling us that our code has gotten into a state we didn't expect. Their appearance often portends bugs. Though we groan at an unexpected stack trace, we should see an error as a form of automated feedback . Feedback can be fast or slow. We can put the discovery of errors onto a timeline. Errors appear at many points over the lifetime of the code, starting at the moment it is compiled. The further to the right that an error appears, the longer it takes for the feedback to appear. Compile time Compile time is the earliest we can receive feedback about an error. The compiler automatically does a number of checks to make sure the code makes some semblance of sense. The most powerful tool for compile-time feedback is the type-checker. The type-checker makes sure that only values of the expected type are passed around to the places that expect them. This guards ...
As hurricanes approach the shores of North America, we are barraged with maps of possible tracks those storms can take. Those tracks start pretty close together, but diverge widely the further into the future they predict. Simplified, those storm tracks form a cone of uncertainty . A storm in the Atlantic could slide into the Gulf of Mexico and land anywhere from the Texas-Mexico border to Panama City Beach, FL. It all depends on a myriad of tiny factors to turn the storm this way or that. As time progresses, the storm moves along, and the cone of uncertainty shrinks. Its eventual location becomes clearer to predict, and we can more effectively target resources. Cone of Uncertainty for Hurricane Ike, source Much like hurricanes, running code lives in a cone of uncertainty. A function or method call is a mysterious black box until we have a result. If something goes wrong, we must delve into this cone of code uncertainty to find the problem. We use log statements and de...
I was recently perusing when I came across a link to a Joel Spolsky blog post . In it, he describes how a form of Hungarian notation can be used to make wrong code look wrong. In the process, he describes the interesting history of how Hungarian notation came to be, and how the common use of it today was not the way it was originally intended. He describes how Hungarian notation was created to convey application-level information about a variable. It could be used to distinguish between two different types of dimensions that might both be typed as int s. He termed this Apps Hungarian. While the compiler could not tell them apart, the human eye would be able to with a cursory glance. Later, the notation was instead conflated with the type that the compiler saw. An int iWidth carried redundant information that could actually get in the way if the type ever needed to change. He termed this Systems Hungarian. He gives several examples in the post. Notably, he describes how Apps Hunga...